



How Computer Science Students Can Build a Personal Knowledge System That Survives the Semester
Computer science courses produce several kinds of information at once. A single week may include lecture slides, textbook chapters, code samples, lab instructions, error messages, research papers, and project discussions.
Most students organize these materials by file type or download date. That works until an exam or project requires an idea that appeared across several places. The problem is not a lack of notes. It is the absence of a system that connects concepts, examples, and decisions.
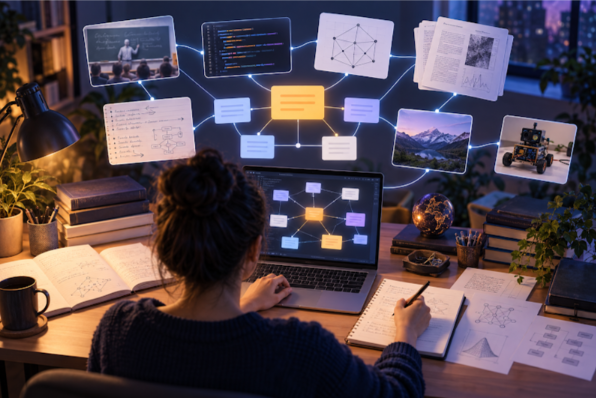
A personal knowledge system solves this by giving every useful item a clear place, a source, and a path back into active study.
Capture four kinds of knowledge
Not every piece of information needs the same treatment. A durable student system separates four categories:
- Concepts: definitions, mental models, formulas, and explanations
- Examples: code snippets, worked problems, diagrams, and test cases
- Experience: mistakes, debugging notes, failed approaches, and lessons learned
- Deliverables: assignments, project plans, reports, presentations, and exam summaries
This separation matters because students reuse each category differently. Concepts support recall, examples support application, experience prevents repeated mistakes, and deliverables show how knowledge was used.
Organize around courses and problems, not apps
A tool should not define the structure of your learning. Start with stable categories that will remain useful if you change note apps or storage platforms.
Use the course as the top level, then create sections for major topics, assignments, and projects. Within a topic, keep the explanation, code example, and related question close together.
For example, a database systems section might contain normalization rules, a schema example, a query that failed, and a note explaining the correction. Keeping these items connected makes revision more useful than storing all code in one folder and all notes in another.
Record the source of every important idea
A note without a source becomes difficult to trust. Record whether an idea came from a lecture, textbook page, paper, documentation site, or discussion with a teammate.
Source links also protect against accidental plagiarism. When writing a report, you can distinguish your interpretation from the author’s claim and cite the original work accurately.
For code, save the language version, library version, and the smallest working example. Technical advice can become outdated quickly, and a snippet without its environment may fail when you need it most.
Turn lectures into questions, not transcripts
Copying every slide creates a record, but it does not create understanding. After each lecture, write three to five questions that the material should help you answer.
A networking lecture might become: Why does TCP retransmit a segment? How does congestion control differ from flow control? What evidence would show packet loss in a trace?
Attach the relevant slide, diagram, or reading to each question. During revision, attempt an answer before opening the source. This converts passive notes into an active recall system.
Keep a debugging journal
Debugging produces some of the most reusable learning in computer science, yet students often discard it once the code runs. Keep a short journal for errors that took more than a few minutes to solve.
For each entry, record the symptom, the incorrect assumption, the test that isolated the cause, and the final fix. The most valuable line is often the incorrect assumption, because it reveals how your mental model needs to change.
Over time, this journal becomes a personal troubleshooting guide. It also gives you concrete material for project reports and technical interviews.
Use AI as a study layer, not a replacement for thinking
AI can explain unfamiliar concepts, generate practice questions, compare approaches, and help summarize long readings. It becomes less reliable when it lacks the actual course material or invents details that sound plausible.
A better workflow gives the AI agent the lecture notes, assignment constraints, code version, and relevant documentation before asking for help. Tools such as remio for students can keep these sources connected, so explanations and drafts are grounded in the materials you already collected.
Ask for evidence with every important answer. A useful prompt is: “Explain this result using my lecture notes and show which source supports each step.” Then verify the cited section yourself.
Never submit generated code you cannot explain. Run it, test edge cases, and rewrite the solution in your own structure. If the result fails, add the failure to your debugging journal.
Build a weekly maintenance routine
A knowledge system fails when capture becomes a large weekend project. Use a small routine that fits into the academic week.
- After each class, capture the key source and write one question.
- After each lab, save one working example and one debugging lesson.
- At the end of the week, connect duplicate notes and remove low-value copies.
- Before starting an assignment, search the system for related concepts and past mistakes.
- After submission, record feedback and update the relevant concept note.
This cycle keeps the system current without turning organization into another course.
Prepare for exams with synthesis, not rereading
Two weeks before an exam, create a topic map that lists the major concepts and their relationships. Mark each concept as explain, apply, or debug.
Explain means you can describe the idea without notes. Apply means you can solve a new problem. Debug means you can recognize and correct a flawed solution. A topic is not complete until you can do all three at the level expected by the course.
Use your saved questions to test recall. Use code examples to test application. Use the debugging journal to review misconceptions that have already cost you time.
Use the same system for projects
For team projects, create a decision log beside the code. Record the options considered, the chosen approach, the reason, and any constraint that may require revisiting the decision.
Connect each decision to the issue, meeting note, or experiment that supports it. This makes the final report easier to write and prevents the team from reopening the same discussion without new evidence.
A project knowledge base should also contain setup instructions, data definitions, test results, and known limitations. Future teammates should be able to understand the system without asking the original author to reconstruct the history.
Avoid the three common traps
The first trap is collecting everything. Save material only when it answers a question, supports a task, or changes your understanding.
The second trap is excessive formatting. A plain note with a clear title, source, and useful explanation is better than a beautiful template you avoid using.
The third trap is trusting search to replace structure. Search is helpful, but clear course, topic, and project boundaries reduce noise and make related material easier to review together.
Let the system compound
A good personal knowledge system becomes more valuable each semester. Data structures connect to algorithms, operating systems connect to networking, and database design connects to software engineering projects.
The goal is not to build a perfect archive. It is to reduce the time between encountering information and using it well. Capture the source, connect the concept, test your understanding, and record what the work taught you.
When that cycle becomes routine, your notes stop being a storage folder. They become evidence of how you think, learn, and solve technical problems.